🪆 Matryoshka MRL · Hybrid Edge/Cloud RAG · Spanish Tax Law

Hacienda-ESP-RAG: Matryoshka Vector Compression & Hybrid Edge Hydration over 36,053 Tax Rulings

How to index 10 years of Spanish Binding Tax Rulings (1.05 GB) on a $0/month cloud footprint by slicing Google EmbeddingGemma vectors by 83.3% (768D → 128D) and hydrating full legal texts in <2ms from a local NVIDIA Jetson Orin Nano.

EmbeddingGemma (Matryoshka MRL) Supabase pgvector (halfvec) NVIDIA Jetson Orin Nano (CUDA) SQLite Local Hydration FastAPI Gemini 3.8 Flash Next.js 16 Cloudflare Zero Trust
🏛️
PETETE Scraper
✂️
4.5k Chunking
🪆
MRL Slice + L2
☁️
pgvector halfvec
⚡
<2ms Hydrate
🧠
Gemini Synthesis
⚖️
Side-by-Side UI
01: Executive Summary & Problem Statement

Why Standard Cloud RAG Breaks at 36,053 Legal Rulings

Interactive Live Laboratory (Spanish & English) Test the live side-by-side benchmark at hacienda.mezapps.com or inspect the edge OpenAPI specification at api-hacienda.mezapps.com/docs. Toggle between ES and EN in the header to query and receive grounded legal synthesis in either language.

When a taxpayer or tax advisor asks an LLM a question about Spanish tax law (IRPF, IVA, Impuesto sobre Sociedades, Sucesiones), standard models frequently hallucinate repealed articles or confuse general statutes with binding administrative doctrine. In Spain, the Dirección General de Tributos (DGT) issues Binding Tax Rulings (Consultas Vinculantes) that legally bind the Tax Agency (AEAT).

However, building a production Retrieval-Augmented Generation (RAG) system over a full decade of official rulings (2016–2026: 36,053 documents, 1.05 GB of raw legal text) immediately hits two architectural walls:

36,053
Official DGT Binding Tax Rulings (2016–2026)
-83.3%
Vector RAM Saved via Matryoshka 128D Slicing
< 2 ms
Local SQLite Cold-Storage Text Hydration
0 MB
Raw Legal Text Stored in Cloud Vector DB
276 MB
Total Cloud Footprint (Fits 500 MB Free Tier)
1.05 GB
Full Legal Corpus Hosted on Edge NVMe
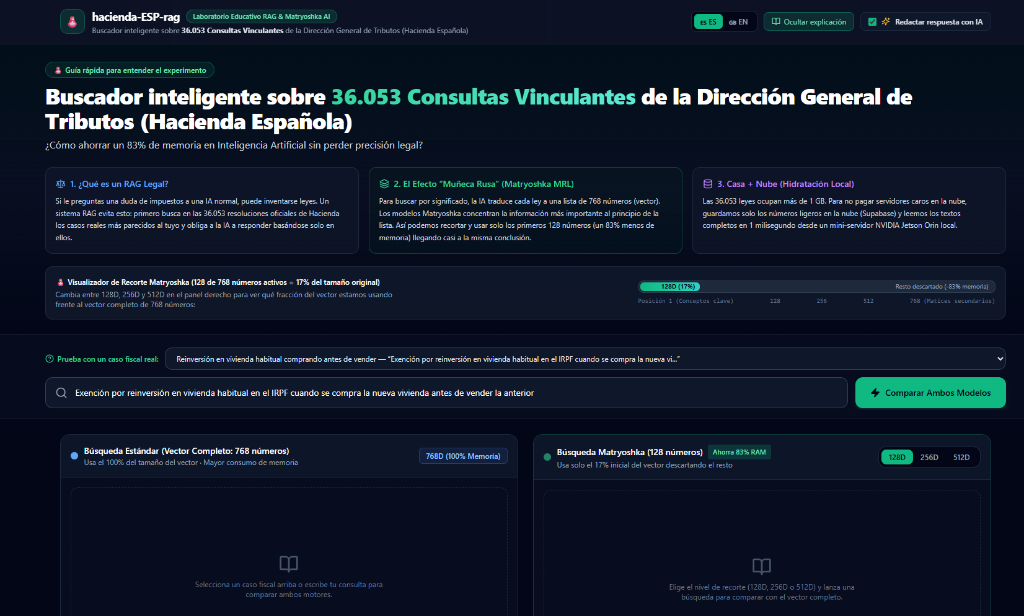
Hacienda-ESP-RAG interactive side-by-side Matryoshka benchmark live at hacienda.mezapps.com

The live educational benchmark at hacienda.mezapps.com comparing full 768D vector retrieval against Matryoshka-sliced 128D, 256D, and 512D embeddings in real time.

02: Data Engineering & Corpus Design

Scraping 10 Years of Spanish Tax Doctrine & High-Signal Legal Chunking

The official Spanish Ministry of Finance doctrine database (PETETE / Knosys) has no public REST API or bulk dataset export. It relies on stateful server-side sessions and legacy HTML forms. To build a complete, reproducible legal corpus from 2016 to 2026, I engineered a custom asynchronous scraping and ingestion pipeline (scraper_petete.py):

⚡ Async Range Scraping & Deduplication

Built with httpx.AsyncClient and BeautifulSoup4 using exponential backoff and year/ID range partitioning. Multiple worker nodes scraped multi-year slices in parallel and merged them via merge_db.py using deterministic SHA-256 content hashes into a single SQLite WAL database.

📐 High-Signal 4,500-Char Legal Chunks

Instead of micro-chunking, documents are segmented into 4,500-character blocks (~1,000 tokens) with a 500-character overlap, stripping repetitive administrative headers so each chunk preserves complete statutory citations and legal reasoning chains.

Contextual Header Injection

When a long ruling is split into multiple chunks, secondary chunks normally lose awareness of which ruling number, tax date, or governing body they belong to. Before computing embeddings on the GPU, the chunker dynamically injects a rich metadata header into every single fragment:

# Dynamic contextual prefix injected into every 4,500-char legal chunk before GPU embedding
header_prefix = (
    f"[Consulta Vinculante DGT {num_consulta} | "
    f"Fecha Salida: {fecha_salida} | "
    f"Órgano: {organo} | "
    f"Normativa: {normativa[:180]}]\n"
)
enriched_chunk_text = header_prefix + clean_legal_body

This single data-engineering decision reduced total vector rows from an estimated ~500,000 down to ~150,000 high-density chunks while dramatically improving retrieval precision for specific statutory articles (e.g., Artículo 38.1 Ley 35/2006 LIRPF).

03: Matryoshka Representation Learning (MRL)

The "Russian Doll" Effect: Cutting Vector Memory by 83.3% Without Re-Indexing

In traditional embedding models (such as text-embedding-ada-002 or standard BERT derivatives), semantic information is distributed uniformly across all 768 or 1,536 vector dimensions. Dropping the last 80% of coordinates destroys the vector's meaning.

Matryoshka Representation Learning (MRL)—used to train Google's EmbeddingGemma—optimizes a nested multi-scale loss function across prefixes of the vector (128D ⊂ 256D ⊂ 512D ⊂ 768D) simultaneously during training. Just like nested Russian dolls, the neural network is forced to pack the highest-variance semantic concepts (the core tax type, transaction structure, and statutory article) into the first 128 dimensions, while dimensions 129..768 encode progressively finer syntactic nuances.

Vector Configuration Active Dimensions Bytes / Chunk (float16) RAM for 150k Chunks Memory Saved Role in Legal Retrieval
Full Vector (Baseline) 768D (100%) 1,536 Bytes ~230.4 MB Baseline (0%) Maximum nuance across all coordinates
Matryoshka Large 512D (66.7%) 1,024 Bytes ~153.6 MB -33.3% RAM Near-100% Top-10 overlap with full 768D
Matryoshka Medium 256D (33.3%) 512 Bytes ~76.8 MB -66.7% RAM High semantic recall at 1/3 memory cost
Matryoshka Core (Ultra-Compact) 128D (16.7%) 256 Bytes ~38.4 MB -83.3% RAM Captures core tax doctrine & reaches identical LLM legal conclusions

The Mathematical Catch: Why L2 Re-Normalization is Mandatory

A full 768-dimensional embedding generated by EmbeddingGemma lies on the surface of a 768D unit hypersphere (‖v1:768‖2 = 1). When we slice the vector to its first d ∈ {128, 256, 512} coordinates, the truncated vector v1:d falls inside the d-dimensional unit sphere (‖v1:d‖2 < 1). To preserve exact cosine similarity ordering via inner-product / cosine operators in pgvector, both the query vector and the database sub-vector must be L2 re-normalized after slicing:

v̂1:d  =  v1:d  /  √( ∑i=1..d vi2 )   ⟹   ‖v̂1:d‖2 = 1
Hypersphere Projection: Projects the truncated prefix v1:d back onto the surface of the d-dimensional unit sphere so cosine similarity (<=>) remains mathematically exact.
def slice_and_normalize_mrl(vec_768: list[float], dim: int) -> list[float]:
    """
    Matryoshka (MRL) prefix truncation + L2 hypersphere re-normalization.
    Ensures exact cosine geometry in R^dim after slicing from R^768.
    """
    sliced = vec_768[:dim]
    norm = math.sqrt(sum(x * x for x in sliced))
    if norm > 0:
        return [x / norm for x in sliced]
    return sliced

On the cloud side, rather than duplicating tables for 128D, 256D, 512D, and 768D, we store a single halfvec(768) (16-bit float) column in Supabase PostgreSQL and perform dynamic SQL sub-vector slicing inside our custom RPC function:

-- Dynamic Matryoshka slicing inside PostgreSQL pgvector (0 duplicate storage)
CASE
    WHEN match_dimensions = 128 THEN
        1 - (subvector(c.embedding, 1, 128)::halfvec(128) <=> query_embedding::halfvec(128))
    WHEN match_dimensions = 256 THEN
        1 - (subvector(c.embedding, 1, 256)::halfvec(256) <=> query_embedding::halfvec(256))
    WHEN match_dimensions = 512 THEN
        1 - (subvector(c.embedding, 1, 512)::halfvec(512) <=> query_embedding::halfvec(512))
    ELSE
        1 - (c.embedding <=> query_embedding::halfvec(768))
END AS similarity
04: Hybrid Edge + Cloud ("Local Hydration")

Zero Text in the Cloud: Pairing Supabase pgvector with a Local NVIDIA Jetson Orin Nano

Even after compressing embeddings with halfvec and Matryoshka slicing, uploading 1.05 GB of raw legal text into a managed cloud Postgres database would immediately exceed the 500 MB Free Tier limit. To keep cloud recurring costs at $0.00/month while serving full 15-page rulings, I designed a Hybrid Edge + Cloud "Local Hydration" Architecture:

❌ Naive Cloud-Only RAG ($70–$150/mo) ✅ Hybrid Edge + Cloud Local Hydration ($0/mo)
Stores float32(768) vectors + 1.05 GB of raw text chunks directly inside Cloud Postgres (>3.5 GB total database size). Cloud Supabase stores ONLY num_consulta + halfvec numbers (0 bytes of text in the cloud; ~276 MB total footprint).
Transfers 45,000+ characters of legal text over the WAN on every Top-10 vector search query. Supabase returns 10 lightweight ruling IDs + cosine scores over the network in a few kilobytes.
Truncates context to the matched 500-char snippet, starving the LLM of the full ruling's conditions. NVIDIA Jetson Orin Nano hydrates the entire 15-page ruling in <2 ms from local NVMe SQLite.
1
GPU Query Embedding on NVIDIA Jetson Orin Nano When a user submits a tax question on hacienda.mezapps.com, the request reaches the Jetson Orin Nano via Cloudflare Tunnel. Local Ollama (CUDA) computes the 768D EmbeddingGemma vector once on the Jetson's Ampere GPU, then slices and L2-normalizes the selected Matryoshka prefix (128D, 256D, or 512D).
2
Parallel Cloud Vector Search (768D vs MRL 128D) The FastAPI backend dispatches both the full 768D vector and the Matryoshka 128D vector concurrently via ThreadPoolExecutor to Supabase pgvector, retrieving the Top-10 unique ruling IDs (Vxxxx-xx) and cosine similarity scores for each engine.
3
Sub-2ms Local SQLite Cold-Storage Hydration With the matched ruling IDs in hand, the Jetson executes a single indexed lookup against its local 1.05 GB consultas_vinculantes.db file on disk. In 1.2 to 2.5 milliseconds, it hydrates the complete full-length Contestación Vinculante, metadata, dates, and cited statutes.
4
Parallel Grounded Legal Synthesis (Gemini 3.8 Flash) Both hydrated legal contexts (768D and 128D) are sent in parallel to gemini-3.8-flash with a strict zero-hallucination system prompt requiring explicit citations of Consultas Vinculantes (Vxxxx-xx) and statutory articles, allowing the user to verify that the 128D (-83.3% RAM) model reaches the exact same legal conclusion.
05: Production Hardening & Cybersecurity

Exposing a Physical Home-Lab GPU Server Safely to the Public Internet

Because the backend runs 24/7 on a physical NVIDIA Jetson Orin Nano inside a residential network and invokes paid LLM synthesis APIs, exposing it publicly required defense-in-depth engineering across the network, application, and OS layers:

🛡️ Cloudflare Zero Trust Named Tunnel

Zero open ports (80/443/8000) on the home router. An outbound-only cloudflared systemd daemon connects the Jetson to Cloudflare's edge (api-hacienda.mezapps.com), providing automatic TLS termination and DDoS mitigation while hiding the residential IP.

⏱️ Dual Sliding-Window IP Rate Limiter

Custom in-memory middleware inspects the cryptographic CF-Connecting-IP header to enforce a two-tier quota: 10 requests/minute (protecting the Jetson's 8 GB shared GPU RAM) and 200 requests/day per IP (preventing automated scraping or Gemini API wallet exhaustion).

🧱 XML Prompt-Injection Sandboxing

User queries are strictly capped at max_length=1500 characters via Pydantic validation and wrapped inside isolated <user_query> XML tags. The system prompt explicitly instructs the model to treat everything inside <user_query> as untrusted tax facts, neutralizing instruction-override attacks.

🔒 OS-Level Read-Only SQLite (?mode=ro)

The FastAPI worker connects to the 1.05 GB legal database using a strict SQLite URI with ?mode=ro. Even in the theoretical event of an application-level vulnerability, the database file descriptor is locked read-only by the Linux kernel.

06: Interactive UX & Legal Verification

Designed for Both Engineers & Non-Technical Visitors (ES / EN)

Most RAG benchmarks are static Jupyter notebooks. I built the frontend (hacienda.mezapps.com) in Next.js 16 (App Router) + Tailwind CSS as an interactive, self-explanatory laboratory:

Project Links 🚀 Live Benchmark App (ES/EN)  ·  💻 GitHub Repository  ·  📘 Live API Docs (Swagger)

← Back to Portfolio